Note
Go to the end to download the full example code.
No-overlap example#
In this example, we use the no-overlap solver on an open dataset of gait (steps) IMU time-series to discover patterns in the data. We will then use those to attempt to detect steps and compare our findings with the ground truth.
Using ‘no-overlap’#
Retrieve trial data
Downloading data from http://dev.ipol.im/~truong/GaitData.zip (192.3 MB)


file_sizes:   0%|                                    | 0.00/202M [00:00<?, ?B/s]
file_sizes:   0%|                            | 24.6k/202M [00:00<18:31, 181kB/s]
file_sizes:   0%|                            | 49.2k/202M [00:00<18:34, 181kB/s]
file_sizes:   0%|                             | 106k/202M [00:00<11:33, 290kB/s]
file_sizes:   0%|                             | 221k/202M [00:00<06:37, 507kB/s]
file_sizes:   0%|                             | 319k/202M [00:00<05:44, 584kB/s]
file_sizes:   0%|                             | 549k/202M [00:00<03:31, 953kB/s]
file_sizes:   0%|                            | 745k/202M [00:00<03:00, 1.12MB/s]
file_sizes:   1%|▏                          | 1.20M/202M [00:01<01:50, 1.82MB/s]
file_sizes:   1%|▏                          | 1.60M/202M [00:01<01:32, 2.16MB/s]
file_sizes:   1%|▎                          | 2.51M/202M [00:01<00:56, 3.53MB/s]
file_sizes:   2%|▍                          | 3.04M/202M [00:01<00:54, 3.67MB/s]
file_sizes:   2%|▋                          | 4.74M/202M [00:01<00:31, 6.24MB/s]
file_sizes:   3%|▊                          | 6.32M/202M [00:01<00:24, 7.86MB/s]
file_sizes:   4%|█▏                         | 8.68M/202M [00:01<00:17, 10.8MB/s]
file_sizes:   6%|█▌                         | 11.8M/202M [00:02<00:13, 14.3MB/s]
file_sizes:   7%|██                         | 15.0M/202M [00:02<00:11, 16.6MB/s]
file_sizes:   9%|██▎                        | 17.6M/202M [00:02<00:10, 17.5MB/s]
file_sizes:  10%|██▋                        | 20.2M/202M [00:02<00:10, 18.1MB/s]
file_sizes:  12%|███▏                       | 23.4M/202M [00:02<00:09, 19.2MB/s]
file_sizes:  13%|███▍                       | 26.0M/202M [00:02<00:09, 19.3MB/s]
file_sizes:  14%|███▉                       | 29.1M/202M [00:02<00:08, 20.1MB/s]
file_sizes:  16%|████▎                      | 31.7M/202M [00:03<00:08, 20.0MB/s]
file_sizes:  17%|████▋                      | 34.9M/202M [00:03<00:08, 20.5MB/s]
file_sizes:  19%|█████                      | 37.5M/202M [00:03<00:08, 20.2MB/s]
file_sizes:  20%|█████▎                     | 40.1M/202M [00:03<00:08, 20.0MB/s]
file_sizes:  21%|█████▊                     | 43.3M/202M [00:03<00:07, 20.6MB/s]
file_sizes:  23%|██████▏                    | 45.9M/202M [00:03<00:07, 20.2MB/s]
file_sizes:  24%|██████▌                    | 49.0M/202M [00:03<00:07, 20.8MB/s]
file_sizes:  26%|██████▉                    | 51.7M/202M [00:03<00:07, 20.4MB/s]
file_sizes:  27%|███████▎                   | 54.8M/202M [00:04<00:07, 20.8MB/s]
file_sizes:  28%|███████▋                   | 57.4M/202M [00:04<00:07, 20.5MB/s]
file_sizes:  30%|████████                   | 60.6M/202M [00:04<00:06, 20.9MB/s]
file_sizes:  31%|████████▍                  | 63.2M/202M [00:04<00:06, 20.4MB/s]
file_sizes:  33%|████████▊                  | 65.8M/202M [00:04<00:06, 20.2MB/s]
file_sizes:  34%|█████████▏                 | 69.0M/202M [00:04<00:06, 20.7MB/s]
file_sizes:  36%|█████████▌                 | 71.6M/202M [00:04<00:06, 20.3MB/s]
file_sizes:  37%|██████████                 | 74.7M/202M [00:05<00:06, 20.8MB/s]
file_sizes:  38%|██████████▎                | 77.4M/202M [00:05<00:06, 20.4MB/s]
file_sizes:  40%|██████████▊                | 80.5M/202M [00:05<00:05, 20.8MB/s]
file_sizes:  41%|███████████▏               | 83.1M/202M [00:05<00:05, 20.5MB/s]
file_sizes:  43%|███████████▍               | 85.7M/202M [00:05<00:05, 20.2MB/s]
file_sizes:  44%|███████████▉               | 88.9M/202M [00:05<00:05, 20.7MB/s]
file_sizes:  45%|████████████▎              | 91.5M/202M [00:05<00:05, 20.4MB/s]
file_sizes:  47%|████████████▋              | 94.7M/202M [00:06<00:05, 20.8MB/s]
file_sizes:  48%|█████████████              | 97.3M/202M [00:06<00:05, 20.4MB/s]
file_sizes:  50%|█████████████▉              | 100M/202M [00:06<00:04, 20.8MB/s]
file_sizes:  51%|██████████████▎             | 103M/202M [00:06<00:04, 20.4MB/s]
file_sizes:  53%|██████████████▋             | 106M/202M [00:06<00:04, 20.8MB/s]
file_sizes:  54%|███████████████             | 109M/202M [00:06<00:04, 20.5MB/s]
file_sizes:  56%|███████████████▌            | 112M/202M [00:06<00:04, 20.9MB/s]
file_sizes:  57%|███████████████▉            | 115M/202M [00:07<00:04, 20.5MB/s]
file_sizes:  58%|████████████████▎           | 118M/202M [00:07<00:04, 20.9MB/s]
file_sizes:  60%|████████████████▋           | 120M/202M [00:07<00:03, 20.5MB/s]
file_sizes:  61%|█████████████████           | 123M/202M [00:07<00:03, 20.2MB/s]
file_sizes:  63%|█████████████████▌          | 126M/202M [00:07<00:03, 20.6MB/s]
file_sizes:  64%|█████████████████▉          | 129M/202M [00:07<00:03, 21.0MB/s]
file_sizes:  65%|██████████████████▎         | 132M/202M [00:07<00:03, 20.5MB/s]
file_sizes:  67%|██████████████████▋         | 135M/202M [00:08<00:03, 20.9MB/s]
file_sizes:  68%|███████████████████         | 138M/202M [00:08<00:03, 20.5MB/s]
file_sizes:  70%|███████████████████▌        | 141M/202M [00:08<00:02, 20.9MB/s]
file_sizes:  71%|███████████████████▉        | 143M/202M [00:08<00:02, 20.5MB/s]
file_sizes:  73%|████████████████████▎       | 147M/202M [00:08<00:02, 20.8MB/s]
file_sizes:  74%|████████████████████▋       | 149M/202M [00:08<00:02, 20.5MB/s]
file_sizes:  76%|█████████████████████▏      | 152M/202M [00:08<00:02, 20.9MB/s]
file_sizes:  77%|█████████████████████▌      | 155M/202M [00:09<00:02, 20.5MB/s]
file_sizes:  78%|█████████████████████▉      | 158M/202M [00:09<00:02, 20.9MB/s]
file_sizes:  80%|██████████████████████▎     | 161M/202M [00:09<00:01, 20.5MB/s]
file_sizes:  81%|██████████████████████▋     | 163M/202M [00:09<00:01, 20.2MB/s]
file_sizes:  83%|███████████████████████     | 166M/202M [00:09<00:01, 20.7MB/s]
file_sizes:  84%|███████████████████████▍    | 169M/202M [00:09<00:01, 20.4MB/s]
file_sizes:  85%|███████████████████████▉    | 172M/202M [00:09<00:01, 20.8MB/s]
file_sizes:  87%|████████████████████████▎   | 175M/202M [00:09<00:01, 20.4MB/s]
file_sizes:  88%|████████████████████████▋   | 178M/202M [00:10<00:01, 20.8MB/s]
file_sizes:  90%|█████████████████████████   | 181M/202M [00:10<00:01, 20.5MB/s]
file_sizes:  91%|█████████████████████████▌  | 184M/202M [00:10<00:00, 20.9MB/s]
file_sizes:  92%|█████████████████████████▉  | 186M/202M [00:10<00:00, 20.5MB/s]
file_sizes:  94%|██████████████████████████▎ | 190M/202M [00:10<00:00, 20.9MB/s]
file_sizes:  95%|██████████████████████████▋ | 192M/202M [00:10<00:00, 20.5MB/s]
file_sizes:  97%|███████████████████████████ | 195M/202M [00:10<00:00, 20.8MB/s]
file_sizes:  98%|███████████████████████████▍| 198M/202M [00:11<00:00, 20.5MB/s]
file_sizes:  99%|███████████████████████████▊| 201M/202M [00:11<00:00, 20.1MB/s]
file_sizes: 100%|████████████████████████████| 202M/202M [00:11<00:00, 17.9MB/s]
Successfully downloaded file to /github/home/data/dicodile/gait/GaitData.zip
Replace is False and data exists, so doing nothing. Use replace=True to re-download the data.
Replace is False and data exists, so doing nothing. Use replace=True to re-download the data.
Replace is False and data exists, so doing nothing. Use replace=True to re-download the data.
Replace is False and data exists, so doing nothing. Use replace=True to re-download the data.
We now store the trials into a unique numpy array X
We then set the parameters of the dictionary learning
# set dictionary size
n_atoms = 12

# set individual atom (patch) size.
n_times_atom = 120

# set regularization parameter
lmbd = 0.1 * n_times_atom / n_times
We are now able to intialize a dictionary using a strategy for the non-overlapping case
from alphacsc.init_dict import init_dictionary

D0 = init_dictionary(
    X,
    n_atoms=n_atoms, n_times_atom=n_times_atom,
    rank1=False, D_init='no-overlap', reg=lmbd
)
The dictionary can be optimized using l0 normalization and assuming no overlap between atoms in the signal encoding as follow
[BatchCDL] CD iterations 0 / 5
[BatchCDL] Objective (z) : 2.052e+04 (sparsity: 3.078e-04)
[BatchCDL] Resampled atom 0
[BatchCDL] Objective (d) : 1.695e+04
[BatchCDL] CD iterations 1 / 5
[BatchCDL] Objective (z) : 1.649e+04 (sparsity: 3.078e-04)
[BatchCDL] Objective (d) : 1.581e+04
[BatchCDL] CD iterations 2 / 5
[BatchCDL] Objective (z) : 1.555e+04 (sparsity: 3.078e-04)
[BatchCDL] Objective (d) : 1.533e+04
[BatchCDL] CD iterations 3 / 5
[BatchCDL] Objective (z) : 1.524e+04 (sparsity: 3.078e-04)
[BatchCDL] Objective (d) : 1.508e+04
[BatchCDL] CD iterations 4 / 5
[BatchCDL] Objective (z) : 1.499e+04 (sparsity: 3.078e-04)
[BatchCDL] Objective (d) : 1.491e+04
[BatchCDL] Fit in 0.5s

<alphacsc.convolutional_dictionary_learning.BatchCDL object at 0x7f903ed8cc20>
Check that our representation is indeed sparse:
nnz = np.count_nonzero(cdl._z_hat)
print("Non zero coefficients count:", nnz)
Non zero coefficients count: 342
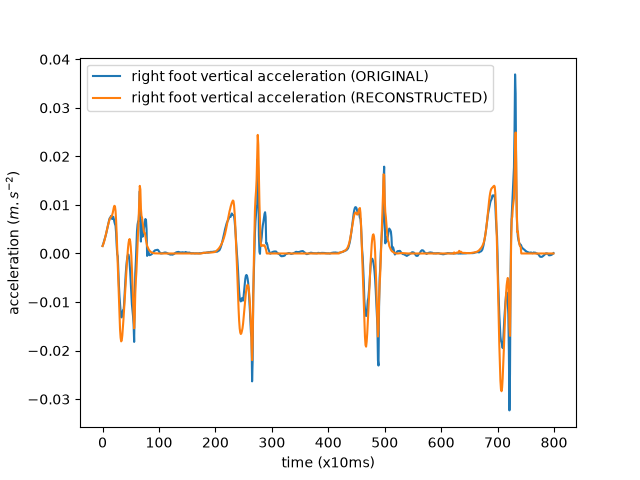
Now, let’s reconstruct the original signal.
from alphacsc.utils.convolution import construct_X_multi

def reconstruct(cdl):
    X_hat = construct_X_multi(cdl._z_hat, cdl._D_hat)
    diff = X - X_hat
    E0 = .5 * diff.ravel() @ diff.ravel() / X.var()
    E = E0 + lmbd * nnz / X.var()
    print("l2-objective:", round(E0, 1))
    print("BatchCDL 'no-overlap' objective:", round(E, 1))
    return X_hat

X_hat = reconstruct(cdl)
l2-objective: 10786.8
BatchCDL 'no-overlap' objective: 14905.5
Plot a small part of the original and reconstructed signals
import matplotlib.pyplot as plt

trial = 0
channel = 0

fig_hat, ax_hat = plt.subplots()
ax_hat.plot(X[trial, channel, 5000:5800],
            label='right foot vertical acceleration (ORIGINAL)')
ax_hat.plot(X_hat[trial, channel, 5000:5800],
            label='right foot vertical acceleration (RECONSTRUCTED)')
ax_hat.set_xlabel('time (x10ms)')
ax_hat.set_ylabel('acceleration ($m.s^{-2}$)')
ax_hat.legend()
plt.show()
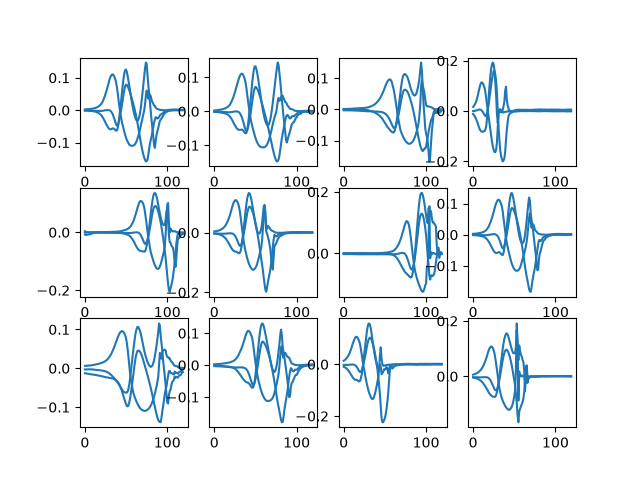
Plot the atoms learned inside the dictionary
from dicodile.utils.viz import display_dictionaries

display_dictionaries(cdl._D_hat)
<Figure size 640x480 with 12 Axes>
Comparisons#
Let’s compare timings and objectives when using different solvers and initializers
import time

lgcd_reg = 4. * lmbd * n_times / n_times_atom / X.std()

args = [
    {"solver_z": 'no-overlap', "D_init": 'no-overlap', "solver_d": 'no-overlap'},
    {"solver_z": 'no-overlap', "D_init": 'no-overlap', "solver_d": 'fista'},
    {"solver_z": 'no-overlap', "D_init": 'random', "solver_d": 'no-overlap'},
    {"solver_z": 'no-overlap', "D_init": 'random', "solver_d": 'fista'},
    {"solver_z": 'lgcd', "D_init": 'no-overlap', "solver_d": 'fista'},
    {"solver_z": 'lgcd', "D_init": 'random', "solver_d": 'fista'},
]

for kwarg in args:
    print(kwarg)
    print("="*len(repr(kwarg)))

    reg = lgcd_reg if kwarg["solver_z"] == 'lgcd' else lmbd / X.var()
    if kwarg["D_init"] == 'no-overlap':
        kwarg['init_kwargs'] = {"reg": reg}
    cdl2 = BatchCDL(
        n_atoms, n_times_atom,
        random_state=42, rank1=False,
        lmbd_max="fixed", reg=reg, n_iter=5,
        verbose=0, **kwarg
    )
    start = time.time()
    cdl2.fit(X)
    fit_time = time.time() - start

    print("time:", fit_time)
    reconstruct(cdl2)
    print()
{'solver_z': 'no-overlap', 'D_init': 'no-overlap', 'solver_d': 'no-overlap'}
============================================================================
time: 0.5506746768951416
l2-objective: 10786.8
BatchCDL 'no-overlap' objective: 14905.5

{'solver_z': 'no-overlap', 'D_init': 'no-overlap', 'solver_d': 'fista'}
=======================================================================
time: 2.287276029586792
l2-objective: 10805.5
BatchCDL 'no-overlap' objective: 14924.2

{'solver_z': 'no-overlap', 'D_init': 'random', 'solver_d': 'no-overlap'}
========================================================================
time: 0.4414181709289551
l2-objective: 11926.1
BatchCDL 'no-overlap' objective: 16044.8

{'solver_z': 'no-overlap', 'D_init': 'random', 'solver_d': 'fista'}
===================================================================
time: 3.956340789794922
l2-objective: 15455.3
BatchCDL 'no-overlap' objective: 19574.0

{'solver_z': 'lgcd', 'D_init': 'no-overlap', 'solver_d': 'fista'}
=================================================================
/github/workspace/alphacsc/learn_d_z_multi.py:317: UserWarning: Regularization parameter `reg` is too large and all the activations are zero. No atom has been learned.
  warnings.warn("Regularization parameter `reg` is too large "
time: 6.739338636398315
l2-objective: 140293.2
BatchCDL 'no-overlap' objective: 144411.9

{'solver_z': 'lgcd', 'D_init': 'random', 'solver_d': 'fista'}
=============================================================
time: 6.528496742248535
l2-objective: 140293.2
BatchCDL 'no-overlap' objective: 144411.9
Total running time of the script: (0 minutes 34.782 seconds)